 889f2fac1d * fix(cline): keep the cost each Cline, KiloCode and IBM Bob request recorded The parser read Cline's per-request cost but never marked it as billed, so the cache dropped it and every read re-priced the tokens at a list price, or at a stand-in model when the task named none. A positive recorded cost now survives the cache; requests without one stay re-priceable. Parse versions bumped for cline, kilo-code and ibm-bob so cached tasks pick the cost up. * fix(cline): key Cline-family tasks on ui_messages.json, not the task directory Cline rewrites ui_messages.json in place, which never moves the task directory's mtime or size, so a growing task kept serving its first cached snapshot. The source is now the file itself; the new path re-parses every task once on its own, so no parse-version bump is needed. * fix(antigravity): keep RPC output tokens when the response/thinking split is absent Generator metadata from the language server omits unset proto3 fields, so an entry carrying only outputTokens was stored and priced with 0 output. The RPC path now reconciles the split the way the SQLite path already does. Results cache v11 and an antigravity parse-version bump re-read cached cascades. * fix(parser): label Devin and Antigravity token-priced costs as calculated Both providers keep the cost they priced from tokens at parse time through the cache, and that kept cost was served with costBasis 'recorded', the label for a tool's own billed figure. They now serve as 'calculated'. Decided at serve time, so cached calls change label without a re-parse and totals are unchanged; serve-time re-pricing still needs the pricing id stored. * fix(warp): put a conversation's new spend on its new exchanges Warp records cost and tokens per conversation, and each parse re-split the running total over every finished exchange, so a later exchange's spend moved onto earlier days. Exchanges already in the cache now keep their share and only the growth since the last parse is split over the new ones. No new state: the previous split is read from the cache entry being replaced. * fix(warp): discover Warp on Linux and Windows Only the macOS group-container paths were tried, so Warp on Linux or Windows reported nothing unless WARP_DB_PATH was set. Adds the default locations from Warp's file-locations docs: $XDG_STATE_HOME/warp-terminal (and -preview) on Linux, %LOCALAPPDATA%\warp\Warp\data on Windows. Both variables join warp's cache fingerprint. * fix(zed): defer a locked threads.db instead of reading it as empty Zed's whole history is one source, so a SQLITE_BUSY on open or on the threads query parsed as zero calls and replaced every cached Zed thread for the run. Busy errors now reach the parse loop, which keeps the cached rows and retries on the next refresh, like the other SQLite providers. * fix(quickdesk): stop counting a session's estimate after its metrics arrive Quick Desktop sources are merged durably, so a sessions.db estimate cached before the session's metrics landed was never removed and the session counted twice from then on. The sessions.db source is now marked as a snapshot of the store, replaced on each re-parse; a locked store defers the parse (cached rows kept, retried next refresh) instead of reading as empty. Parse version bumped so cached double counts re-parse. * fix(grokbot): keep requests that slide out of Grok Bot's mirror window The app mirrors only about the last 200 transcript entries per bot, and each re-parse replaced the cached calls with the current window, so older requests vanished from live views as a busy bot kept working. Grok Bot sources are now durable: requests the window dropped stay cached, ones still in it are refreshed in place. * fix(vercel-gateway): keep the cached report when a refresh cannot fetch it An unreachable gateway, a rate limit or a server error parsed as an empty report, so the run showed $0 of gateway spend with nothing but a stderr line. Those failures now defer the source the way a busy SQLite store does: the cached report keeps serving, the run is marked not fully hydrated, and the next refresh retries. A refused credential still reads as no report. * fix(grokbot): make only the mirror slices durable, not the import source Marking the whole provider durable also kept a removed usage import's rows, so removing an import no longer restored the local figures. Durability is now a per-source override (SessionSource.durable, which replaces the snapshot flag from the Quick Desktop fix): Grok Bot's mirror slices merge, Quick Desktop's sessions.db replaces, and orphan handling stays with the provider. * test(warp): expect the platform's own Warp candidates in probe roots * fix(cline): keep a recorded zero cost at zero A request Cline recorded at cost 0 (a free model) was re-priced from tokens into a positive charge. Any recorded cost, zero included, is now kept; only a request with no cost field is priced from its tokens. * test(warp): pin per-conversation allocation of new spend Each Warp conversation is its own source and keepCachedWarpShares only sees that source's cached entry and calls, so one conversation's growth can never land on another's new exchanges. Two conversations gaining exchanges together, only one with billed growth, now pin that. * fix(warp): probe Warp's Linux paths only on Linux Every non-macOS, non-Windows platform fell through to the Linux locations. Candidates are now exact per platform: macOS bundles, Linux state dirs, Windows LOCALAPPDATA, and none elsewhere. * fix(vercel-gateway): stop retrying a gateway that keeps failing every refresh A permanently unreachable gateway (DNS failure, persistent 5xx) deferred every refresh forever: stale rows served, the run never fully hydrated. A network source now counts consecutive retryable failures on its cache entry; the third marks it failed with its rows kept, so it serves those rows without fetching until the next day (a credential change still invalidates it) and shows in doctor as a cached failure. A successful fetch resets the count. * fix(warp): split fresh when a cached exchange disappears When an exchange the cache held is no longer in Warp's table, the kept shares no longer add up to the reported total and the gap went wholly to the latest exchange. A current exchange set that is not a superset of the cached one now discards the cached split and splits the current total fresh. * fix(vercel-gateway): treat 408, 409 and 425 as retryable report failures A request timeout, conflict or too-early answer was read as a definitive empty report. They now keep the cached report and retry like 429 and 5xx: the statuses Vercel's own AI SDK retries, plus 425, which asks for a retry. * test(grokbot): a removed import's rows go while the mirror's rows stay * test(cline): a task cached under its old directory key is evicted, not doubled * test(warp): two conversations in one database are allocated independently A Warp source is exactly one conversation: discoverFromDb (src/providers/ warp.ts) emits one source per agent_conversations row with path '<db>:<conversation_id>', the parser reads only rows WHERE conversation_id = ? for that id, and parser.ts hands keepCachedWarpShares only section.files[source.path], the cache entry of that one conversation. Nothing is pooled across conversations. Pinned with the case where A gains $3.75 and an exchange while B gains a zero-spend exchange: A's new exchange carries $3.75, B's $0. * test(vercel-gateway): pin every retryable status and the refused-credential case * fix(cline): re-read a task when api_conversation_history.json changes The Cline-family source is ui_messages.json, but the task's model and workspace come from api_conversation_history.json. A history file written after the first parse never moved the fingerprint, so the task kept its stand-in model and pricing. The fingerprint of a ui_messages.json now folds in the sibling's inode, mtime and size, a missing sibling being its own state, while ui_messages.json stays the source key. * fix(antigravity): let the output total win whenever the split disagrees Rule: ModelUsageStats' output total (field 3 / outputTokens, documented as thinking + response) is authoritative whenever it is set. The existing reconciliation already trusted it over a disagreeing split, but skipped the case where thinking alone exceeded the total, so outputTokens 100 with thinking 200 and response 50 kept 250. That case now caps thinking at the total and leaves response at 0. One shared helper applies the rule on the RPC and SQLite paths; the unreleased rpc-output-total-v1 bump already re-parses cached cascades. * fix(antigravity): apply the output-total rule to a total of 0 as well A record with output total 0 beside a nonzero thinking/response split kept the split, against the total-wins rule. Antigravity never writes that shape: a read-only scan of every gen_metadata row in the owner's Antigravity conversation databases (166 rows, 9 files) found 165 whose split sums exactly to the total and none with a zero total beside a nonzero split. The .pb conversations are readable only through the running app, so they were not scanned. A total of 0 now caps the split at 0 like any other total. * fix(antigravity): keep the split when the output total is absent The previous commit treated a missing output total like an explicit 0 and cut a recorded thinking/response split down to nothing. An absent total (no outputTokens key on the RPC path, field 3 not set in the SQLite proto) now keeps the split as before; a total that is present, 0 included, still wins over a split that disagrees. Same rule on both paths. * fix(antigravity): treat an unreadable output total as absent An RPC usage entry whose outputTokens is present but not a number (an empty string) was reconciled as NaN and produced NaN output. A total that does not parse to a finite number now counts as absent and the split stands. On the SQLite path a varint cannot be non-numeric; a field 3 of the wrong wire type (no varint value) is likewise treated as absent. * fix(warp): bump the parse version so cached databases take the share rule An unchanged Warp database kept serving calls split by the old re-spread, because nothing invalidated its cache entry. exchange-share-v1 re-parses it once; the version is pinned in a test. Also pins that a conversation whose exchanges are no longer finished clears its cached calls: keepCachedWarpShares returns the empty set before reading any call, since every cached key is then missing from the current set. * test(warp): a cached conversation with no current exchanges yields no calls |
||
|---|---|---|
| .claude-plugin | ||
| .github | ||
| .oss-scanner | ||
| .semgrep/rules | ||
| app | ||
| assets | ||
| dash | ||
| docs | ||
| gnome | ||
| mac | ||
| perf | ||
| plugins/codeburn | ||
| scripts | ||
| src | ||
| tests | ||
| vscode | ||
| windows | ||
| .editorconfig | ||
| .gitignore | ||
| .gitleaks.toml | ||
| .nvmrc | ||
| .release-0.9.21-runbook.md | ||
| BRIEF.md | ||
| CHANGELOG.md | ||
| CODE_OF_CONDUCT.md | ||
| codeburn-desktop-wireframes.html | ||
| CONTRIBUTING.md | ||
| LICENSE | ||
| package-lock.json | ||
| package.json | ||
| README.md | ||
| RELEASING.md | ||
| SECURITY.md | ||
| server.json | ||
| SUBMISSION.md | ||
| SUPPORT.md | ||
| THIRD_PARTY_NOTICES.md | ||
| tsconfig.json | ||
| tsup.config.ts | ||
| vitest.config.ts | ||
|

|
See where your AI spend goes.



If CodeBurn shows you something your bill never did, star the repo so other developers find it, and consider sponsoring to keep 42 integrations honest.
npx codeburn
To keep it: npm install -g codeburn or brew install codeburn. Needs Node.js 22.15+.


The macOS builds are signed with a Developer ID and notarized by Apple.
The problem
Your bill gives you a month total. It does not break that down by project, by model or by task, and it does not show which part of it was wasted.
Claude Code, Codex, Cursor and the rest each write a session file every time you use them, and those files hold every token and every model call. CodeBurn reads those files and produces the breakdown.
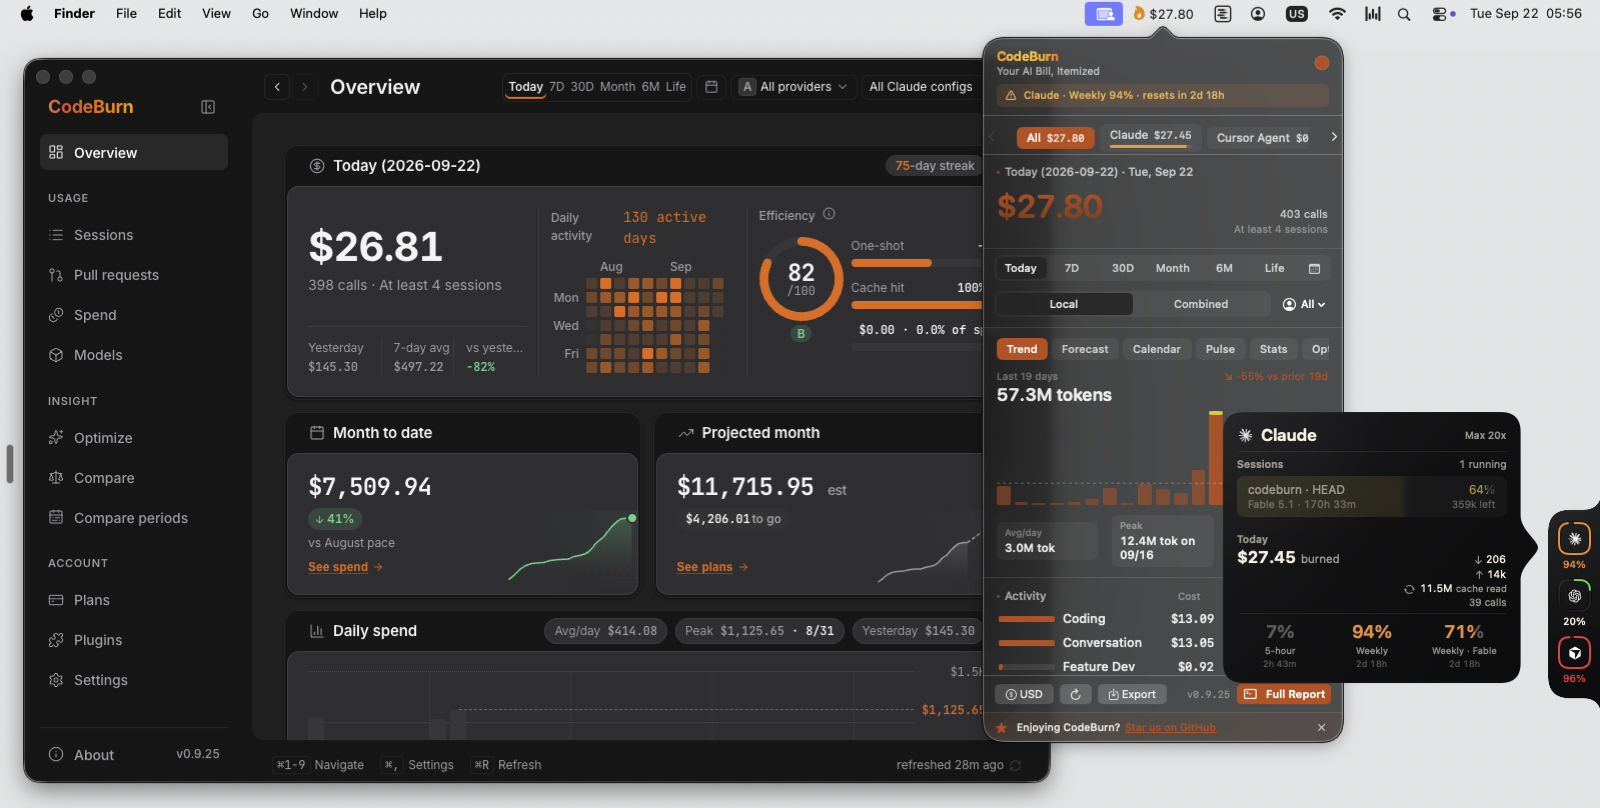
Desktop app, macOS menu bar, Capacity Dock and the Claude glance card, one engine behind all of them.
Sixty seconds
npx codeburn
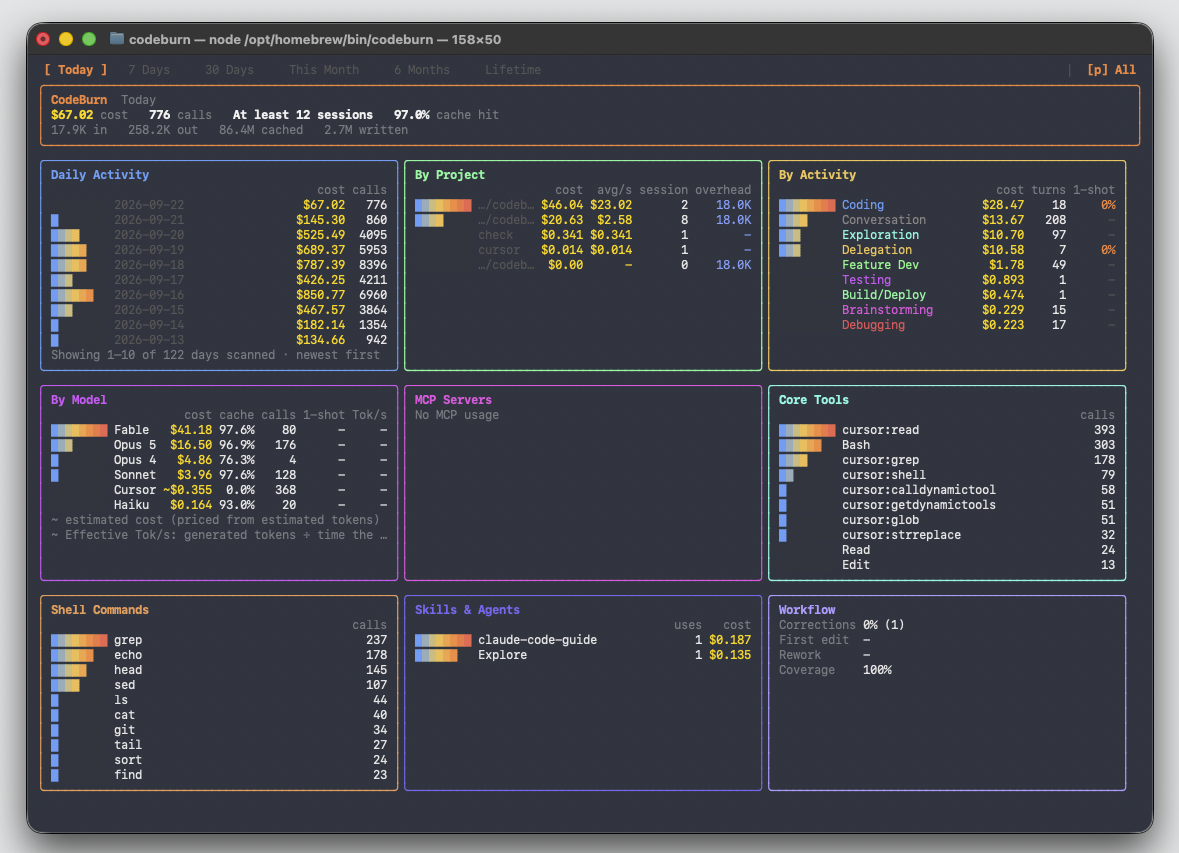
There is no account and no sign-up. CodeBurn looks in the folders your tools already write to, prices every token, and prints what you spent.
Under the total are the tables: cost by tool, by model, by project and by task. Task means what the agent was doing, such as coding, debugging or planning, worked out from the session itself.
Arrow keys move the period, from today out to your whole history. Press p to switch between tools. Press q to quit.
See it
The desktop app is the same data with room to move around in. It opens on today: what you have spent, what the month is on pace to cost, and the last thirty days day by day.
One click from the clock, the menu bar popover shows the short version of that page. The Capacity Dock adds a ring per provider at the screen edge. Hover a ring and a glance card tells you what is running right now and which limits are filling up.
All four read the same files on your disk, so they show the same numbers, allowing for when each one last refreshed.
The same numbers are in your browser with codeburn web, and in the terminal with codeburn.
Understand it
Every number in the app is clickable. Click today's total and you land on Sessions, one row per session with its project, its model, its tokens and its cost. Click a row and you get the turns inside it, so you can see which part of the work was expensive.
On the Spend page the same money is cut four ways, by project, by git branch, by model and by task. The branch view adds up every session you ran while you were on that branch, so you get the cost of a feature.
Compare periods puts two date ranges side by side and shows the difference. Use it after you change something, a model or a workflow or a prompt, to find out whether the change actually cost less.
The Pull requests page matches spend against the pull requests your sessions recorded, so you can see which spend shipped (Yield).
Fix it
codeburn optimize
Optimize reads your sessions and your config, then lists what costs tokens without earning them. A file the agent re-reads on every turn. An MCP server you installed months ago and never call. A CLAUDE.md that grew long enough to ride along in every single request.
Each finding comes with a grade, the fix, and what that fix should save you over the period it scanned.
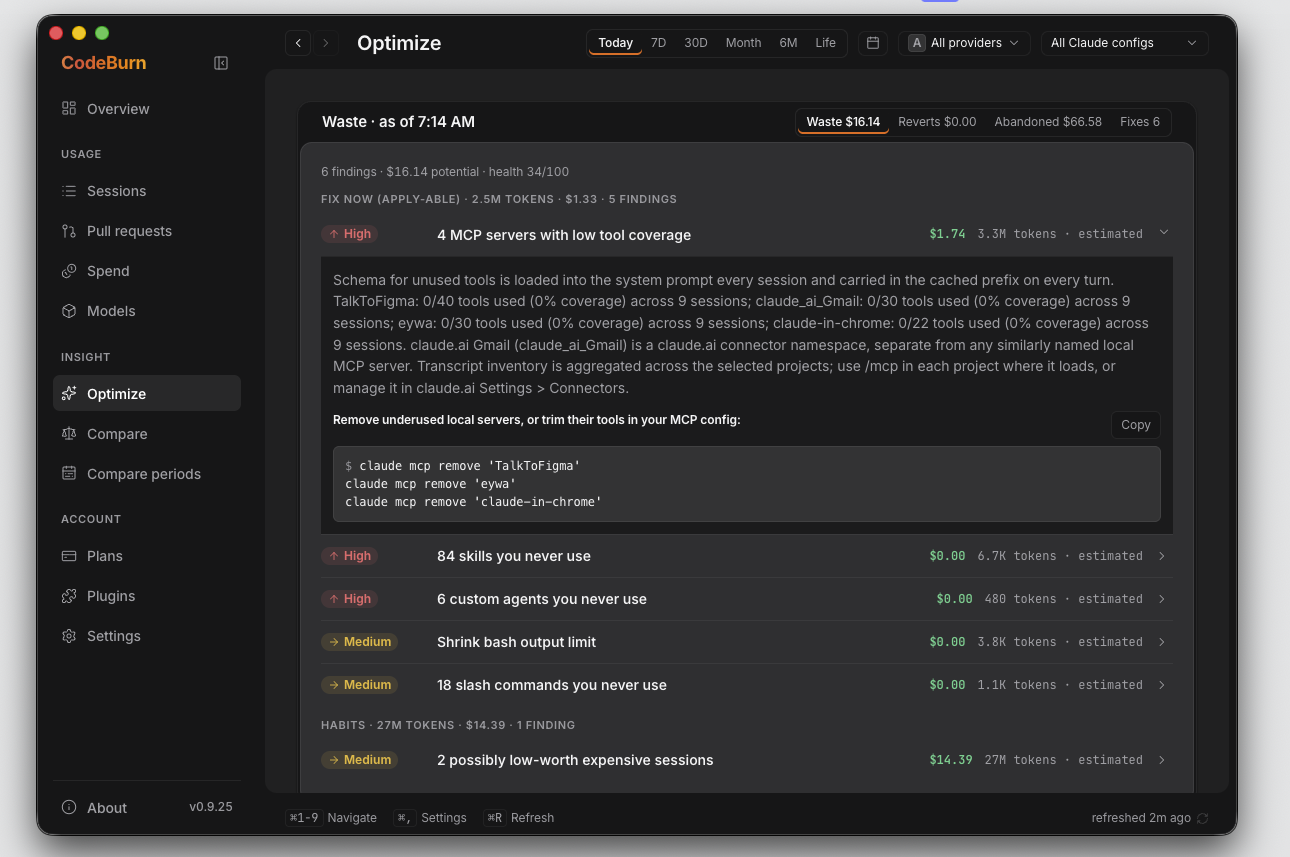
CodeBurn can make the config changes for you, and take them back:
codeburn optimize --apply   # review and apply
codeburn act undo --last    # put it back
Files are backed up before they are changed, and you see the change before anything is applied. A few days later, codeburn act report checks what each fix promised against what your sessions actually did, including the fixes that changed nothing.
Stay ahead
codeburn plan set claude-max   # the plan you pay for
codeburn quota                 # how much of it is left
codeburn guard install         # spending caps for Claude Code
Tell CodeBurn which subscription you pay for and it stops showing only what you spent. It shows how much of the plan you have used, and whether the month is on pace to run past it.
codeburn quota reads the live limits out of the tools you are already signed in to. That is where the five-hour and weekly windows come from. Check it before a long run.
Guard is opt-in and local. codeburn guard install adds Claude Code hooks that warn a session once it passes $5 and stop it at $15, and do the same for a tool call stuck in a loop or a failing command retried over and over. All the limits are yours to change, codeburn guard status shows where the hooks live, and codeburn guard uninstall takes them out again.
Always in view
Today's spend sits in the macOS menu bar, beside the clock. Click it and the popover opens on the same figures as the app, with today, the period switcher, the trend and the per-model breakdown.
The Capacity Dock docks a thin rail to any edge of your screen, with one ring per provider showing how much of that plan is left. It shows what is left before you start a run, not after.
Turn either on from the desktop app's Plugins page in one click, or from the command line:
codeburn menubar
On Linux the same view lives in the top panel, as a GNOME Shell extension.
The desktop app runs on Windows. Install it from the Microsoft Store, which is the recommended way and keeps itself up to date, or take the direct installer. The Windows tray app shows today's cost next to the clock, the same way the macOS menu bar does, and clicking it opens the same popover. The Capacity Dock is there too, from the tray menu or the app's Plugins page. If you run your agents inside WSL, CodeBurn reads the distro's home directory as well as your Windows profile, so sessions you ran in Linux are counted without you installing anything twice.
Setup for all three platforms, including WSL, is in Menu bar and tray.
Inside your agent
In Claude Code, install the plugin. It sets up the MCP server below and adds /codeburn:cost, which summarizes today's spend:
/plugin install codeburn --marketplace getagentseal/codeburn
Or register only the MCP server:
claude mcp add codeburn -- npx -y codeburn mcp
That registers a local MCP server over stdio. Your agent can then answer "where did my tokens go this week" or "what should I change to spend less" without you leaving the conversation.
It reads the same files on disk that the CLI reads. The server answers from that local data and makes no network call of its own, and project names are pseudonymized unless the agent asks for them.
Works with 42 tools
CodeBurn detects the tools you already use. There is nothing to configure and no folder to point it at. If a tool is installed and has sessions on disk, it shows up. Each logo links to that tool's page.







All 42 tools
Each page lists where that tool keeps its data, the format it uses, and the quirks CodeBurn works around.
Amp · Antigravity · Claude Code · Cline · Cline CLI · Codebuff · Codex · CodeWhale · Command Code · Copilot · Crush · Cursor · Cursor Agent · DeepSeek Harness · Devin · Droid · Forge · Gemini CLI · Goose · Grok Bot · Grok Build · Hermes Agent · IBM Bob · KiloCode · Kimi · Kimi Code · Kiro · LingTai TUI · Mistral Vibe · Mux · OMP · Open Design · OpenClaude · OpenClaw · OpenCode · Pi · Qwen · Quick Desktop · Warp · ZCode · Zed · Zerostack
CodeBurn also reads the Vercel AI Gateway reporting API, which is a gateway rather than a tool, so its spend is shown on its own row and left out of your totals by default.
If several of these have sessions on disk, press p in the dashboard to move between them. A path that has changed is worth an issue. Adding a tool is a single file: see src/providers/codex.ts.
Private by design
CodeBurn reads files that are already on your disk. There is no account, no API key and no proxy in front of your agent.
Your prompts, your code and your project names stay on your computer. CodeBurn does not sit between you and your agent, so if it stopped working tomorrow your tools would not notice.
Prices come from LiteLLM and refresh once a day.
Everything that does leave your machine is listed in Privacy.
Built in the open
MIT licensed. Development happens in this repo.
Starred by developers at




Keeping 42 integrations working takes constant time. The tools underneath change often, and each change means a config path to follow or a stored format to relearn. Sponsorship pays for that work.

Companies sponsor at Bronze, Silver or Gold. Your logo goes in a sponsors block in this section, separate from the stargazer badges above. Silver and Gold also put it on codeburn.app. Gold puts it at the top of this README as well, and issues your team files get triaged first. The first company sponsor has the space to itself until the next one shows up.
The manual
| Page | What is in it |
|---|---|
| Commands | Every command, every flag, every keyboard shortcut |
| How it works | Pricing, task categories, and where each tool keeps its data |
| Optimize | What is scanned, what --apply writes, how to read the grade |
| Menu bar and tray | macOS, Windows (including WSL), and the Linux GNOME extension |
| VS Code extension | Status bar, summary and dashboard in VS Code, Cursor, Windsurf, Antigravity and VSCodium |
| Plans and quota | Subscription tracking and live provider limits |
| Guard | Budget caps for Claude Code |
| Web dashboard | The browser view, and combining usage across your devices |
| Yield | Which spend actually shipped, correlated against git |
| MCP | The local MCP server and its two tools |
| Configuration | Currency, model aliases, price overrides, environment variables |
| Tools | One page per tool: data location, format, known quirks |
| All docs | The full index |
Questions
My spend
I know what the month cost. How much of it was wasted, and how would I know?
Run codeburn optimize. It reads the last 30 days of sessions and your ~/.claude/ config, lists what cost tokens without earning them, and prints a Potential savings line in tokens and dollars for the period it scanned. Findings come in three groups: Fix now, which CodeBurn can apply for you, Habits, which is how you drive the next session, and FYI, which may well be money well spent. Each finding says whether its number is measured from your own token counts or modelled from an average. The setup gets a grade from A to F, and that grade rates the config, not the spending, so an expensive month with a clean setup still scores an A. See Optimize.
Which sessions burn the most, and why?
The desktop Overview and the terminal dashboard both list the five most expensive sessions. Click one in the app and you land on Sessions with the drawer open on it: project, models, tokens, and the per-model, per-category, per-branch and per-day split of that one session. codeburn sessions is the same list in the terminal. codeburn optimize flags sessions that cost more than twice their own project's average. The drawer usually shows the cause, such as one model doing most of the work or one category taking most of the turns. See Drill-through.
My agent spent an hour on a five-minute task. Where did the money go?
Open that session in the Sessions drawer for the per-turn cost, then run codeburn context and pick it from the list. codeburn context prints what filled the context window: assistant split into text, reasoning and tool calls with a row per tool, user split into text, images and compaction summaries, and tool with the tool-result total, which is usually the biggest line. It also counts how many compactions happened, which is the usual sign of an hour spent re-reading. The block sizes are estimated from character counts. The exact context figure comes from the last call's reported usage, and the output labels it as such.
Is Opus worth it, or would Sonnet have done the same job?
Run codeburn compare, or press c in the dashboard, to put two models side by side on your own history: one-shot rate, retry rate, self-correction, cost per call, cost per edit, cache hit rate. Cohorts mode narrows that to the same kind of work, one row per edit turn, with median and P90 cost per edit turn and the sample list you can read yourself. Turns that mixed two models are excluded and counted, never assigned to one. codeburn optimize goes further and prints a Model defaults recommendation when a project has enough edit turns to judge: a cheaper model you already used there whose one-shot rate held up, applied with codeburn act apply-model <project>. See Cohort comparison.
Which project costs the most, and which branch inside it?
Open the Spend page and pick a project in the By branch panel. Each branch row shows its cost, calls, tokens, distinct sessions and activity window, attributed turn by turn, so a session that switched branches lands on both rows with its own slice instead of counting twice. From the terminal the same report is codeburn spend --format branch-json. Branch is recorded per turn by Claude Code and by almost nothing else, so the coverage note under the rows splits the project three ways: spend on named branches, spend before a branch was recorded, and spend from tools that carry no branch at all. See Spend by branch.
Do my subagents cost more than they save?
codeburn sessions --by-work-unit gives one row per orchestration root with its delegated children folded underneath, so the parent and its fan-out read as one number. codeburn models --by-agent splits each model's spend by the Claude subagent that drove it, with main sessions and other tools bucketed under main. The dashboard has a Claude Agent Types panel with calls and cost per agent type, and Delegation is one of the task categories. CodeBurn tells you what the fan-out cost. Whether the same work would have been cheaper in one long session is not something it can measure.
What did that pull request cost me?
The app has a Pull requests page, and codeburn sessions --by-pr is the same report in the terminal. It groups spend by the PR links your sessions recorded, and expanding a row takes you to the sessions behind it. Turns that touched more than one PR contribute their share to each, so the rows are not an exclusive split, and spend tied to no PR is labeled rather than hidden. The links come from what the session wrote down, so CodeBurn never calls GitHub and never checks whether the PR merged. For that part, codeburn yield correlates sessions with commits and sorts the spend into productive, reverted and abandoned, and the Overview's Cost per outcome panel shows cost per commit and cost per productive session. See Yield.
Subscriptions and limits
I pay a flat fee for Claude Max. Why does CodeBurn show me dollars?
The dollar figure is what your tokens would have cost at API rates. It is not an invoice. The card labels it API-equivalent, not a live provider window. It is still the only per-session, per-project, per-model number you can get on a subscription, because a subscription gives you one price and no breakdown. Run codeburn plan set claude-max and the Plans page then shows what you have spent this cycle as a share of the plan, and whether you are on track or on pace to exceed it. See Plans and quota.
I keep hitting my 5-hour or weekly limit. Can I see it coming?
codeburn quota asks each provider how much of your plan is left, signing the request with the credential that tool already stores on your machine. For Claude that is a 5-hour row and a weekly row, each with a percentage used and a reset time, shown as 42% used · resets in 3h 20m on the Plans page's Live quota panel. The Capacity Dock carries the same reading, and the macOS menu bar can carry a second line with quota remaining and its countdown. CodeBurn does not predict the hour you will run out. What you get is how full the window is and when it clears.
Is my plan the right size, or am I paying for capacity I never use?
Set what you pay for with codeburn plan set claude-max, or claude-pro, cursor-pro, copilot-pro, google-ai-pro, or custom --monthly-usd 200 --provider codex. The Plans page then shows spend this cycle against that budget with a pacing line, either On track or on pace to exceed with the projected figure and the date. After two or three cycles the pattern is clear. Consistently under a quarter of the plan means you are buying capacity you do not use, and consistently over means the cheaper plan is costing you. CodeBurn shows the share and the pace, and leaves the choice of plan to you.
Three tools, three subscriptions. What is my real total?
Plans are stored per provider, so codeburn plan set claude-max, codeburn plan set cursor-pro and a custom Codex plan sit side by side rather than blending into one figure. codeburn plan prints them all, and the app carries one card per active plan with its own spent, percentage and overage. The spend tables stay per tool underneath, so you can see which subscription is carrying the work and which one is idle. Copilot is tracked in AI credits rather than dollars, because credits are what Copilot actually meters.
How my agent works
My agent reads the same file twenty times. How do I see that and stop it?
codeburn optimize has a detector for exactly this, reported as "Claude is re-reading the same files" with the files and what the re-reads cost. Next to it sit reads into node_modules, .git and dist, and sessions that edit far more than they read first. Those two are the ones a written rule can fix: codeburn optimize --apply appends a marker block to the current project's CLAUDE.md, shows you the file before it writes, and backs it up under ~/.config/codeburn/actions/. codeburn act undo --last puts it back. The re-read finding itself has no file to edit, so the fix there is how you open the next session.
How much of my context is tool output, and what is it costing me?
Run codeburn context and pick a session. It works for Claude Code and Codex, and gives you a tree: assistant split into text, reasoning and tool calls with a row per tool, user split into text, images, compaction summaries and meta, then tool with the tool-result line, and system. The headline shows the exact context size from the last call's usage next to the model's window. The tree counts tokens rather than dollars, because that context is re-sent every turn and its price depends on how much of it came from cache. For the dollars over a period, codeburn models prices the same sessions.
Which MCP servers and skills am I paying for but never using?
codeburn optimize compares what is configured against what was actually invoked. It names MCP servers configured but never called, servers with many tools and almost none used, and skills, agents and slash commands that are defined and never invoked. An MCP server's tool schemas ride along in the prompt whether you call it or not, so an unused one costs tokens on every turn. codeburn optimize --apply removes the server entry from ~/.claude.json or the project's .mcp.json, and moves unused skills into ~/.claude/skills/.archived/ rather than deleting them.
How often does my agent actually get it right first try?
The one-shot rate. It is the One-shot figure on the app's Overview, a column in the dashboard's activity table, and a per-model row in codeburn compare. A retry is counted when the same file is edited again after a shell command ran in between, which is the shape of an edit that did not work. Editing a different file after a shell step is not a retry. Coding at 90% means nine edit turns in ten needed no second pass. File-level tracking works for Claude, Codex and Goose. Other tools fall back to tool names, so their figure is rougher. See How it works.
How does CodeBurn know a session was coding rather than debugging or planning?
From the tools the session used and the words in your own messages, with no model call anywhere. Edit and Write make it Coding. Error and fix words alongside tool use make it Debugging. pytest or vitest in a shell command makes it Testing. Read and Grep with no edits make it Exploration, and the Agent tool makes it Delegation. There are 13 categories and the rules are deterministic, so the same session always lands in the same category. The full table is in How it works.
Trust the numbers
On a subscription the dollars are an estimate. What is estimated and what is measured?
The tokens are measured for most tools. Claude Code, Codex, Gemini, Zed, OpenCode and others write real per-call input, output and cache counts into their own session files, and CodeBurn reads those rather than guessing. The price applied to them is published API pricing, so the dollar figure is arithmetic on measured tokens, not a guess about your bill. A few tools record no counts at all, so Cursor, Kiro and some Copilot sessions are estimated from content length, and those are marked estimated in the tables. Claude Code also bills some calls it does not write to its transcripts: some advisor calls, and subagent replies that keep only part of their usage. For those, CodeBurn can show less than Claude Code's own cost counter. codeburn audit prints a row per provider and model saying where every number came from.
The JSON outputs say it per call. export -f json gives every record a costBasis of recorded (the tool's own figure), calculated (measured tokens at published prices), estimated (guessed tokens), included (covered by a subscription, $0) or unpriced (no known price, $0), and sessions, days, sessions --format json and MCP get_usage carry the share of cost from each of the first three. Since codeburn.export.v3 the JSON uses fixed camelCase keys (cost, apiCalls, inputTokens, ...) with the currency stated once in currency.code; CSV headers are unchanged. New keys like this can still appear under v3.
Where do the prices come from, and what if a vendor changes them?
From LiteLLM, fetched and cached for 24 hours under ~/.cache/codeburn/, so a change reaches you within a day of LiteLLM picking it up. The common Claude and GPT models also carry bundled fallback prices, so a lookup miss falls back to a known rate for those. Anything else shows as unpriced rather than guessed. If a model shows $0 its name matched no price row. codeburn models --unpriced lists those ids, codeburn model-alias points a proxy-rewritten name at the real model, and codeburn price-override sets exact rates yourself. On an enterprise agreement, codeburn price-discount set <provider|model|model:kind> <percent> takes your contracted percentage off calculated costs, while recorded costs stay as the tool billed them. A session is priced with today's rates when it is read, not with the rates of the day it ran. See Configuration.
Claude Code deletes its sessions after 30 days. Does my history go with them?
The daily numbers do not. CodeBurn keeps a durable daily history under ~/.cache/codeburn/, holding each day's cost, tokens and per-project and per-model split for ten years, so codeburn report and codeburn status keep answering for days whose transcripts are gone. The per-session detail does go, because it only ever lived in the transcript. So anything that reads sessions, codeburn sessions, models, spend and compare-periods, will show less for an old range than report does for the same range. Compare periods lists those days by name with their unexplained amount instead of quietly folding them into the totals.
What actually leaves my computer, and how can I check?
Model prices are fetched from LiteLLM and cached for 24 hours, so that call happens at most once a day. codeburn quota asks each provider you are signed in to how much of your plan is left, using the credential that tool already stores on your machine. If you set a non-USD currency, exchange rates come from Frankfurter, cached the same way. If you use Cursor, CodeBurn downloads your own usage export from cursor.com with the Cursor app's login, at most about once an hour, so Cursor figures match your bill; nothing is uploaded, and CODEBURN_CURSOR_SYNC=0 or "cursorSync": false in ~/.config/codeburn/config.json turns it off. Commands that install something, such as codeburn menubar, reach GitHub releases, which is the point of them. Your prompts, your code, your file names and your project names are read on disk and never sent anywhere, and nothing else leaves unless you point CodeBurn at a destination yourself. It is not a proxy, so no traffic of yours passes through it. You can watch what does leave with a network monitor.
Everything else
I work on a laptop and a desktop. Can I get one number across both?
Yes, on the same local network. On the second machine run codeburn share --pair, which opens a pairing window and prints a PIN. On your main machine run codeburn devices add to find it and pair with that PIN, then codeburn devices shows combined totals by machine. codeburn devices rm <name> forgets one again. Sharing stops after ten minutes idle unless you pass --always, and pairing never leaves your network. You can also discover and pair from the browser dashboard at codeburn web. See Web dashboard.
Can my agent read these numbers itself, without me leaving the conversation?
Register the local MCP server with claude mcp add codeburn -- npx -y codeburn mcp. It runs over stdio and exposes two tools: get_usage for spend and usage broken down by tool, model, project and task, and get_savings for the waste findings, retry tax and routing waste, which is the slower of the two. Any MCP client works, with command npx and args -y codeburn mcp. It reads the same files on disk the CLI reads, and project names are pseudonymized unless the agent asks for the real ones. See MCP.
Why is this free, and what is going to cost money later?
CodeBurn is MIT licensed and all of it is in this repository: the CLI, the desktop app, the menu bar and tray apps, the GNOME extension. There is no account, no paid tier and no feature held back for one. It is free because it reads files you already have, which costs nothing to run. What it does cost is time, because 42 integrations sit on top of tools that change their config paths and data formats without warning. Sponsorship is what pays for keeping up with them.
Telemetry
What the desktop app sends, and how to turn it off
The CLI sends nothing. No wrapper, no proxy, no phoning home.
The desktop app, the macOS menu bar and the Windows tray can send an anonymous usage report. Telemetry is on by default in every region. The Windows tray asks once, with Accept and Decline. The desktop app and the macOS menu bar start with it on, and Settings turns it off at any time (on desktop: Settings > Privacy & data > Anonymous telemetry). A choice you already made is kept. Turning it off stops all sending, clears anything queued, and mints a fresh install id so past and future reports cannot be linked. What is sent is listed below.
The only identifier is a random id generated on your machine. Events carry the calendar day, never a clock time. Alongside each batch go the app version, platform, architecture and country.
usage_snapshot goes out at most once per calendar day. It is computed by the CLI so the app
and the tray report the identical shape, and every magnitude in it is a bucket, never an exact
figure. The daily report includes the names of the models, tools, skills and MCP servers you use,
alongside those bucketed counts.
| Field | What it carries |
|---|---|
schema, period |
Snapshot version, and the period label you were looking at (for example 30 Days) |
providerCount, costBucket |
How many providers had usage, and total spend as a range: <1, 1-10, 10-50, 50-200, 200-1k, 1k+ USD |
models |
Up to 8 model names, each with its cost bucket, turn-count bucket, one-shot rate, and up to 6 task categories with a turn bucket and share of that model's turns |
categories |
Up to 12 task category names (Coding, Debugging, Planning, …) with a turn bucket, one-shot rate, and up to 3 model names |
providers |
Up to 8 provider names with a cost bucket each |
mcpServers, skills, tools |
Up to 12 names each with a call-count bucket: 0, 1-10, 10-100, 100-1k, 1k+ |
sessions |
Session count bucket, and median session length as a bucket: <5, 5-15, 15-60, 60-240, 240+ minutes |
efficiency |
Cache hit rate and retry tax as shares of the total, to two decimals |
The other events are name-only:
| Event | Fields |
|---|---|
app_open, app_close |
Session length in whole minutes |
section_view |
Which section you opened (overview, spend, …) |
cold_start |
Milliseconds to the first painted overview, and whether it timed out |
cli_error |
Error kind, the command name, how long it ran as a range (<1s to 120s+), the exit code or signal, a reason label (lock-busy, oom, eacces, enoent, network, parse, shutdown, serve, other) picked on your machine from the error text, which is never sent, and the provider when the read was for one provider. Capped at 20 per kind per day |
provider_read_fail |
A provider whose data could not be read: its name, the stage (locate or parse) and the error kind (eacces, busy, enoent, malformed, error). Once a day per provider, stage and kind |
update_result |
How a one-click update went: the version before and after, and ok, download_fail, verify_fail or install_fail. Also sent by the macOS menu bar app and the Windows tray |
optimize_apply |
The finding id you took a fix for (unused-mcp, claude-md-too-long, …) and the fix type |
plan_set |
Provider and plan preset id |
export |
Format (csv or json) and provider |
compare_view |
The two model names being compared |
settings_change |
Setting name and its new boolean or enum value |
Never collected: prompts, code, file contents, file or folder names, project names, branch names, working directories, session titles, PR links, API keys, exact dollar amounts, exact counts, clock times, or IP-based location beyond the country. The names of the models, tools, skills and MCP servers you use are collected, as the table above sets out, and a whitelist sanitizer drops anything that is not a short string, a finite number or a boolean before it leaves the machine.
To turn it off: press Decline on the Windows tray's notice, or open Settings > Privacy & data and switch Anonymous telemetry off.
License
MIT.
CodeBurn is an AgentSeal open-source project and is not affiliated with CodeBurn Bt. or codeburn.hu.
Credits
Pricing data from LiteLLM. Exchange rates from Frankfurter.
Built by AgentSeal.
The Capacity Dock's provider-usage tracking was informed by CodexBar by Peter Steinberger (@steipete), an MIT-licensed menubar app for AI provider usage. Thanks.